Cold steel hums in the dark. Somewhere behind glass doors and guarded corridors, rows of servers blink in rhythmic, voiceless pulses, converting human speech, hospital charts, traffic flows, and factory logs into strings of ones and zeros. Most people hear "artificial intelligence" and picture a clever chatbot trading witty lines on a screen. They picture electricity, silicon chips, and sleek headquarters. They rarely picture what sits underneath those algorithms before a single prediction is made.
Data.
Without it, even the sharpest mathematical model is an engine with no fuel, a library with blank pages, a chef standing in an empty pantry. Over the last decade, the race to build smarter machines has often looked like a mad scramble for computing power and talent. Yet as artificial intelligence moves deeper into public hospitals, municipal grids, manufacturing floors, and everyday commerce, a quieter, heavier question presses down on policymakers and engineers alike: Who actually governs the raw memory of a nation, and what happens when that memory is scattered across thousands of locked vaults?
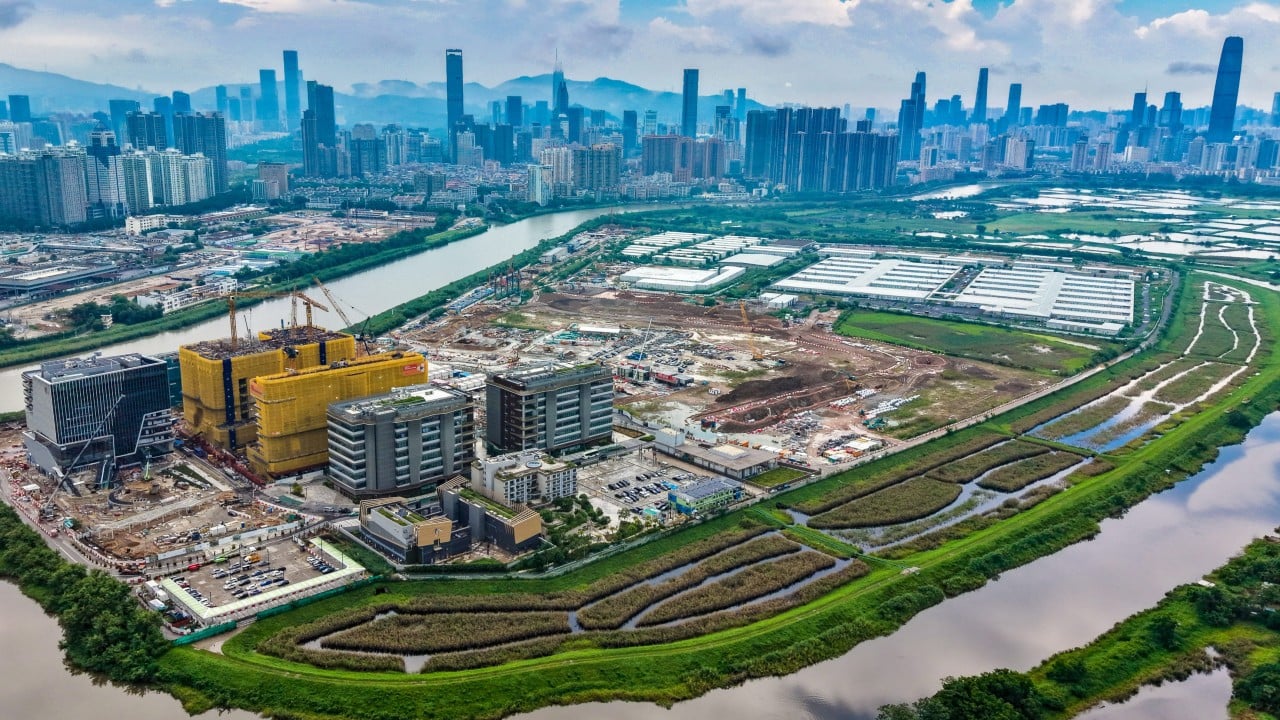
To see why that question has moved from boardrooms to state planning desks, look at Xiongan New Area in Hebei province, roughly a hundred kilometers southwest of Beijing. Announced in 2017 as a grand, long-term blueprint for urban innovation and relieving non-capital functions from the crowded center of Beijing, Xiongan has spent years rising out of wetlands, farmland, and construction sites. Now, by establishing a state-owned firm in Xiongan dedicated to developing the nation's AI data resources, China is treating data not merely as a byproduct of apps and clicks, but as strategic infrastructure—something to be organized, standardized, secured, and put to work at scale.
The Invisible Bottleneck Behind Every Smart Machine
When I first started watching data pipelines up close years ago, what struck me wasn't the glamour of neural networks. It was the sheer messiness of the input. You walk into an operations room expecting sleek order and instead find spreadsheets named final_v3_REAL.xlsx, sensor feeds dropping packets every Tuesday afternoon, duplicate patient records, and databases that refuse to speak the same language.
Data is messy. It is trapped in silos.
Think of a large country's information ecosystem as a vast network of private wells dug on separate farms. One farmer has rich groundwater for wheat; another has water suited for orchards; a third has water tainted by salt or silt because nobody ever mapped the aquifer. Even if every farmer wants to grow more food, nobody can irrigate the whole valley efficiently when the water sits behind locked gates or comes out in incompatible formats. (This well-and-aquifer comparison is a metaphor meant to illustrate how fragmented datasets limit collective utility.)
In plain terms, AI data resources are the structured, clean, labeled, and usable collections of text, images, video, audio, scientific records, and operational logs used to train and run artificial intelligence systems. Having lots of raw data is not the same as having usable data resources. Uncleaned or inaccessible information slows model training, skews accuracy, and forces teams to spend months wrangling files instead of solving real problems.
A hypothetical scenario helps show how this plays out on the ground. Picture a mid-sized regional hospital in a provincial city—let's call it Lin, a fictional data engineer working alongside clinical staff in a hypothetical scenario to make the technical friction concrete. Lin spends weeks trying to help doctors spot early warning signs of sepsis or respiratory decline using historical records. The hospital has years of charts, lab results, and imaging notes. Yet half the fields are typed as free text with local shorthand, older machines exported files in outdated formats, and privacy rules rightly block careless copying. Before any model can learn safely or reliably, someone has to turn messy records into high-quality, compliant data resources while protecting patient dignity.
Multiply Lin's headache across thousands of hospitals, factories, logistics hubs, and public agencies, and the stakes sharpen. If data stays fragmented, smaller institutions fall behind, duplicate work wastes energy and money, and AI systems risk learning from narrow or uneven slices of reality.
Why Xiongan Became a Testbed for State-Backed Data
Why plant a state-owned firm focused on AI data resources in Xiongan rather than in an established tech hub already bursting with startups and skyscrapers?
Geography and design tell part of the story. Xiongan was conceived from the start as a planned modern city—a canvas where digital networks, smart urban systems, and administrative functions could be built cleanly rather than retrofitted onto centuries-old streets. Putting a state-backed data enterprise there ties data development directly to long-horizon state planning, public infrastructure, and coordinated governance.
Consider what happens next: when a state-owned enterprise steps into data resource development, its incentives look different from a purely commercial platform. A private company naturally optimizes for its own products, user retention, or proprietary moat. A state-owned firm tasked with developing national data resources sits at the intersection of public policy, industrial upgrade, and security oversight. Its mandate is typically framed around building foundational data infrastructure, improving data circulation and quality, supporting public and industrial AI applications, and keeping sensitive assets within trusted guardrails.
Still, I don't pretend this is simple or free of tension. Honest observers have to admit how knotty data governance really is. Where does helpful coordination end and over-centralization begin? How do you unlock high-value data for innovation without trampling privacy, commercial secrets, or local initiative? If rules are too rigid, data sits idle; if rules are too loose, trust erodes overnight. Anyone who claims those trade-offs are already solved is selling a fairy tale.
Turning Raw Records Into Public and Industrial Power
To understand what a firm built for AI data resources actually does beyond press releases, strip away the jargon and follow the lifecycle of information.
First comes collection and integration—bringing together relevant datasets from consenting or authorized sources without creating chaotic duplicates. Next comes cleaning, structuring, and labeling—stripping out noise, standardizing formats, and adding context so machines understand what they are looking at. Then comes governance and circulation—setting permissions, anonymization or security controls, and pathways so approved researchers, enterprises, and public systems can use the data responsibly rather than hoarding it in silence.
Imagine a logistics coordinator—let's call her Mei, another hypothetical character in a fictional scenario—trying to cut empty miles for freight trucks moving goods between inland manufacturing towns and coastal ports. Right now, route planning often relies on partial snapshots: one carrier knows its own fuel burn, a warehouse knows its dock delays, a weather feed warns of rain, and highway sensors track congestion. When those pieces stay locked inside separate walls, trucks sit idling or drive half-empty. When cleaner, better-integrated data flows safely under clear rules, routing shifts from guesswork to precision.
That shift has real human texture. Less diesel burned means cleaner air along crowded corridors. Fewer stalled shipments mean fresher produce and steadier paychecks for drivers who aren't stuck waiting on preventable bottlenecks. It is easy to treat "data circulation" as dry administrative plumbing, yet plumbing is what keeps a house warm when winter hits.
The Stakes Beneath the Headlines
A dry news brief can make a corporate creation look like just another line item in a state registry. Yet looking closely at the timing reveals a bigger strategic arc. As global competition around AI increasingly hinges on compute access, model efficiency, energy supply, and proprietary or sovereign datasets, treating domestic data as a cultivated resource—rather than an accidental pile of files—signals a deliberate push to strengthen the base of the pyramid.
There are real advantages to doing this systematically. Standardized, high-quality datasets can speed up scientific research, support smarter public services, lower barriers for smaller domestic AI builders who cannot scrape or buy vast datasets on their own, and embed security and compliance from the ground up.
At the same time, real risks accompany any sweeping state-led push into data. Over-engineered bureaucracy can slow down fast-moving technical teams. Poorly matched datasets can produce brittle models even when the volume looks impressive on paper. And around the world, every major economy wrestling with AI is learning the same hard lesson: data is not oil. Oil gets burned once and disappears; data can be copied, misused, misread, or leaked if guardrails fail—and its value depends heavily on context, consent, and upkeep.
What lingers for me, after years of watching technology promises collide with messy reality, is how quiet the real turning points are. No fireworks. No sci-fi robots marching down an avenue. Just a new entity in a newly built city, working through schemas, permissions, servers, and rules that will shape which questions get answered—and whose world gets reflected—when the machines of tomorrow are trained.
A single cable clicks into a rack, carrying a million quiet choices about what a nation remembers.